Cheatsheet Pages / Regex Cheatsheet
Why you should not parse HTML with regex
Nested tags, comments, CDATA and malformed markup will defeat any pattern eventually — HTML is not a regular language.
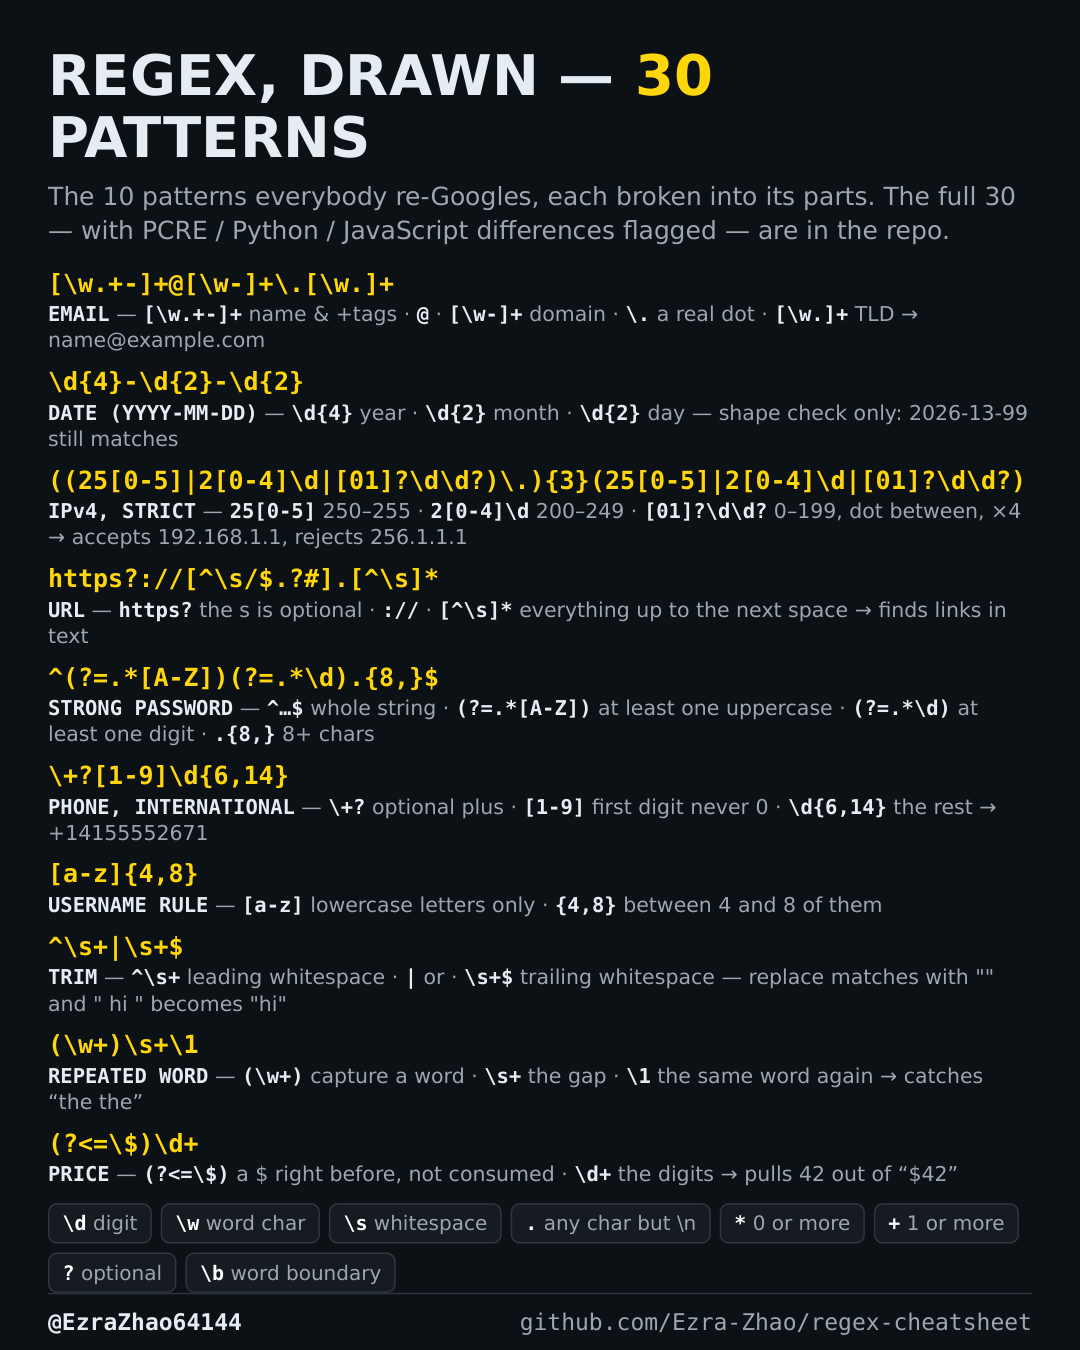
Patterns use the syntax shared by PCRE / Python / JavaScript; engine differences are flagged in the cheatsheet where they matter. Test any pattern at regex101.com — and pick the matching engine.
# <[^>]+> is fine for a quick grep — it is NOT an HTML parserGood to know
Use a real parser: BeautifulSoup (Python), cheerio (JS), or Go's x/net/html. A tag-spotting pattern is fine for a quick grep — it is not a parser.